Servers and cloud infrastructure
We administer the servers and cloud environments your applications live in. System updates, backups with tested restores, disk space, certificates and performance, all watched with automatic alerts.
Your business runs on software, and someone has to watch that it keeps running. We take on your servers and your applications: monitoring with automatic alerts, backups with restores we test, updates applied on time, and incidents with a named owner. That covers software we built and software you inherited from somebody else.
A technical team becomes accountable for your systems staying up: the servers your software runs on, the web applications your business works in every day, and the connections between them. Continuous monitoring, backups, updates, and incidents resolved on terms you signed.
The starting point is usually the same. Something the business depends on is running, and nobody is watching it. A customer notices the outage before you do, the backups are an article of faith nobody has tried to restore, and the provider who built the thing has stopped returning calls.
An automatic alert when something goes down, plus backups, updates and incident handling.
Keeping a published app alive belongs here too, and that sits on the page for mobile app development.
We administer the servers and cloud environments your applications live in. System updates, backups with tested restores, disk space, certificates and performance, all watched with automatic alerts.
Systems that talk to each other need someone watching the conversation. Versions move, endpoints change, and a sync can fail quietly for weeks. It pairs with the integration work on our custom software page.
Your provider closed, retired or stopped replying, and your business still depends on their program. We audit it, document it and take over its maintenance, so it stops being a black box with a missing owner.
A plan worth paying for covers all four, weighted for what you actually run. Most of them cover one.
We maintain software we wrote, which is laid out on custom software development, and software somebody else wrote.
Our working day opens hours before yours, which is useful at exactly the hour you want it to be. What gets covered, which systems count as critical and the response times attached to them are set in your maintenance plan and signed before anything starts.
Cristian Fernández is CTO of STRADA DEV. He writes the maintenance plan, he is the escalation point when an incident goes sideways, and he is the person on your review call.
Calls go on the calendar between 8 and 11 a.m. Eastern, which is the stretch where both teams are at their desks. Something you send first thing gets picked up the same business day.
Here is what the engagement puts in your hands.
Your customer portal, your internal tools and whatever custom platform your staff logs into every morning are systems too. When one of them slows down or goes stale, people notice long before a report does.
Keeping a published mobile app alive belongs here as well, and that part sits on mobile app development.
Monitoring runs around the clock and the alert fires the moment something stops answering.
Tested on a schedule, not assumed.
One owner and one agreed response time per system, both in writing.
Security updates get applied on a cadence instead of whenever somebody remembers.
Servers, applications and the connections between them answered by the same team, so nobody gets to point at the other vendor.
A fee set in writing, with what it covers and what it does not.
We inventory your systems, their state, their risks and whatever documentation exists. You get a plain report on what is weak, and a fixed price for the plan.
Scope per system, priorities, coverage and response times. It lands in your inbox in writing, and nothing starts until you sign it.
Access, credentials and documentation get put in order, including for software we did not write. Your systems end up documented and under control.
Continuous monitoring with automatic alerts, and incidents handled on the agreed terms. One channel to ask for help, and an owner for each one.
What happened, what we did, and what is worth tackling next. Improvements go in small phases, each quoted on its own.
Scope, hours and coverage in writing, with response times set by how critical each system is. This is the usual model when the business depends on the software every day.
For a small footprint, or as a first step to start working together. Hours get used as they are needed and you see where each one went.
Need continuous engineering capacity inside your own team instead? That is team augmentation. In either model, how everything is built and how it would be handed over is written down, so your systems do not depend on us being here.
Mainstream tooling, on purpose. Anything we set up should be legible to the next engineer who opens it, including one who does not work for us.
This service earns its fee fastest where an hour of downtime has a dollar figure attached. Production and shop floor systems for manufacturers, dispatch and tracking platforms for logistics, storefronts and the integrations behind them for ecommerce, production environments for SaaS companies, and one standard across every site for multi-location operators.
Illustrative, not case studies. One of them is probably why you are on this page.
01Situation
The firm that wrote the order system closed its doors, and nobody has touched it in two years because nobody knows what would happen.
What we do
Audit it, write it down, then take over maintenance on a preventive plan. It stops being a black box with no owner.
02Situation
The customer portal went down Saturday morning. Everyone found out Monday, from a customer.
What we do
Monitoring from outside the network with automatic alerts, and corrective response times set per system in the plan you sign.
03Situation
A system the company depends on works fine, but every small change turns into a two week negotiation because nobody wants to be the one who broke it.
What we do
Document it, get real preventive work in place, and put the changes you keep postponing on a phased plan. Control comes back a phase at a time.
Real builds, with the scope and the technical decisions written up. The rest are on our case studies.

We built the software side of this one, and the orders it handles do not wait. The scope and the technical decisions are in the full case.
See the project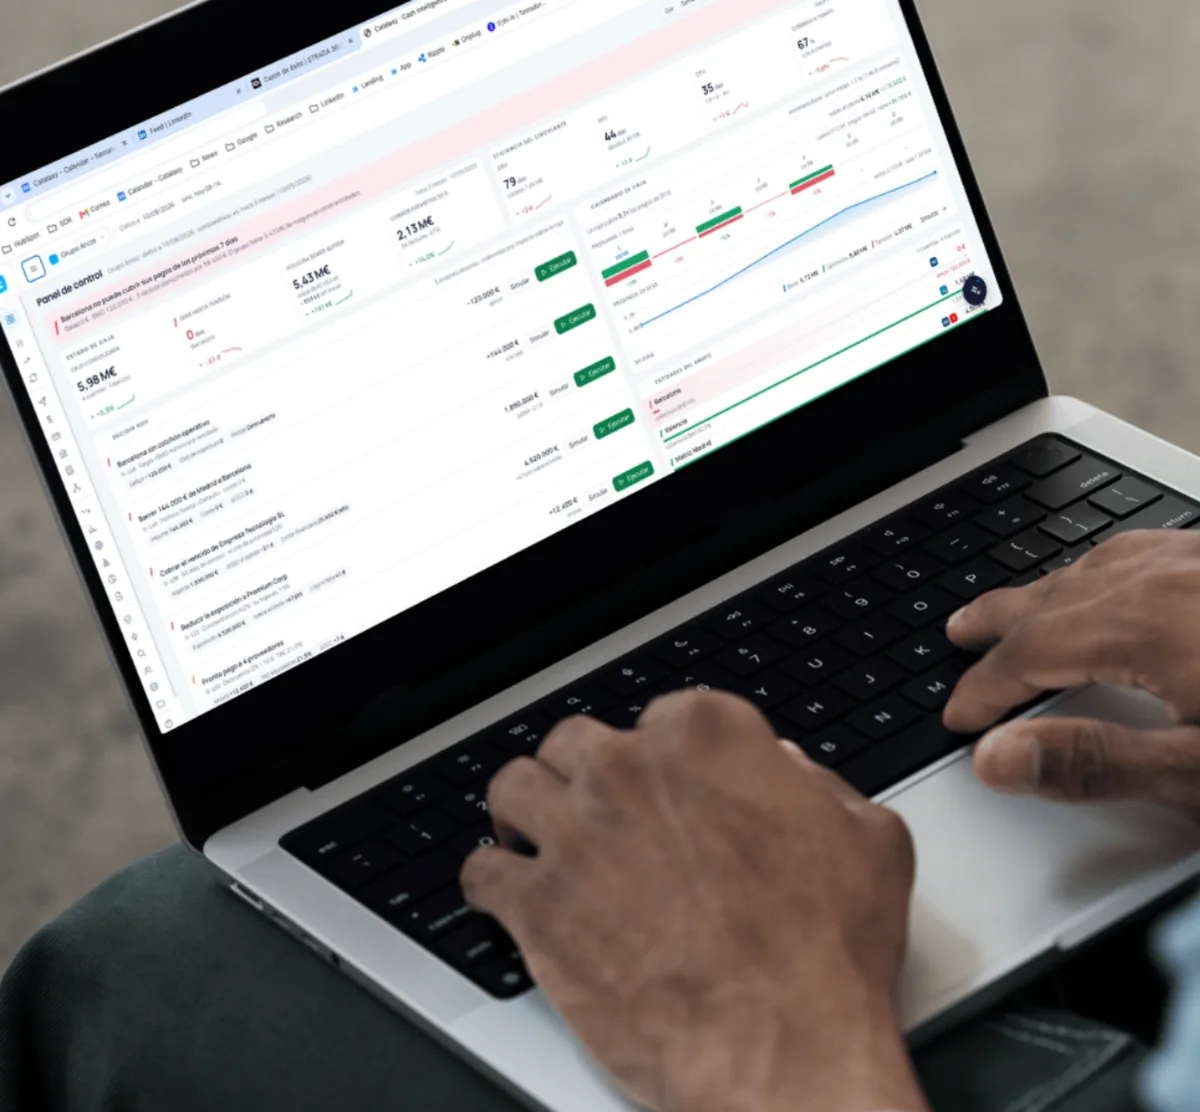
Close to twenty modules in one cockpit, used daily for forecasting and reconciliation. A platform that size is a maintenance job from the day it ships.
See the projectNo two footprints look alike, so the fee gets calculated on yours. Six things move it.
The fee gets quoted after the audit, because a number set before anyone opens your systems is a guess. To put it in context, run the math with your own figures: what the company bills in a day, times the days it would take to come back up. Then add the payroll sitting idle and the customers who bought somewhere else that week.
The audit timeline goes in the proposal in writing. After that, the plan starts when you say so, with its scope and its response times on paper.
Contracting managed services means giving someone access to your systems. Here is what we put in writing to earn it.
No ticket queue in between. The engineer monitoring your systems is the one who knows how they are built.
How the environment is put together and how it would be handed over, documented as we go. That includes software we did not write.
What the plan covers, what response times come with it, and what falls outside. You read all three before you sign.
If your software is at the end of its life, maintaining it is renting time. You get a phased replacement plan instead.
Contracting managed services means giving someone access to your systems. These three questions decide it.
Tell us what you runYes, and a good share of the work arrives that way. We start with an audit to understand the system, document it, and take over maintenance in stages. Who wrote the code matters less than getting it documented and under control.
The ones in your signed maintenance plan. They are set system by system, by how critical it is and by the coverage you contract. One thing is the same for everyone: each incident has an owner with a name on it.
Yes, and the terms go in writing when you sign: what documentation you receive, how the handover runs and on what dates. Access to your systems is yours from day one. We would rather you stay because the service works, and the exit is ready in case you decide otherwise.
That question organizes every other one: which backups exist, when they were last restored, and who picks up the phone on a Saturday. Tell us how it is set up today. You hear back within one to two business days and we work out where to start. For the security side, start with a cybersecurity audit.
Write to us